01 / COMPUTE
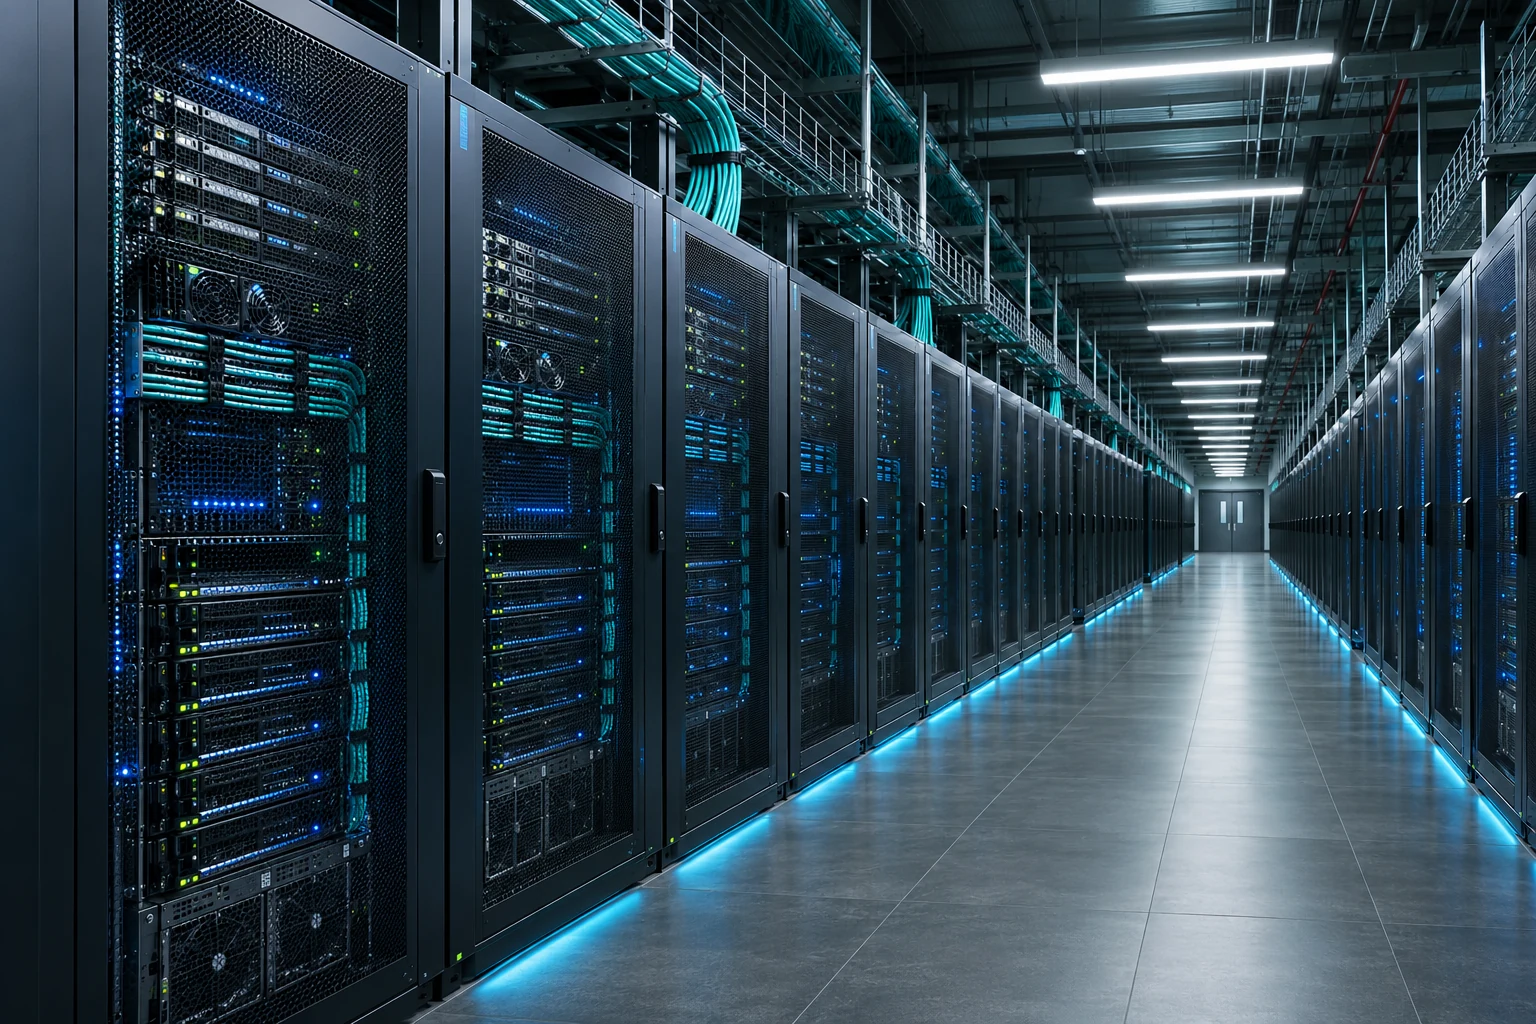
Accelerated compute
GPU clusters and specialised accelerators for model training, fine-tuning and inference.
What it helps you do Match hardware and cluster design to workload demand and deployment schedules.
Plan AI deployments around the systems they depend on. From accelerated compute and data centre capacity to power, cooling and high-speed connectivity.
 View full image
Decisions about capacity, facility design, energy and connectivity affect one another. Evaluating them together helps identify constraints before they become costly to change.
GPU clusters and specialised accelerators for model training, fine-tuning and inference.
Site selection, rack density, colocation and capacity planning for AI workloads.
Utility access, power distribution, resilience and air or liquid cooling requirements.
Cluster fabrics, carrier access, cloud interconnect and connections between facilities.
Explore the infrastructure requirements for three common deployment scenarios.
Plan accelerator density, high-bandwidth interconnect and sustained power for distributed training. Evaluate cooling and maintenance access alongside cluster expansion.
Assess facility location, private connectivity, operational control and data residency requirements before selecting capacity.
Place capacity closer to users or data sources. Balance response latency, regional demand and redundancy when choosing deployment locations.
A practical sequence for scoping an AI infrastructure project, whether it starts with a single cluster or a multi-site expansion.
Establish compute demand, data movement, availability needs and delivery milestones.
Compare site readiness, utility timelines, cooling limits and network options.
Identify dependencies and phase procurement, commissioning and expansion.
For confidential enquiries about WorldAIInfrastructure.com, contact World Domain Centre.